Zyphra ZHA: hierarchical sparse attention with subquadratic complexity for long context
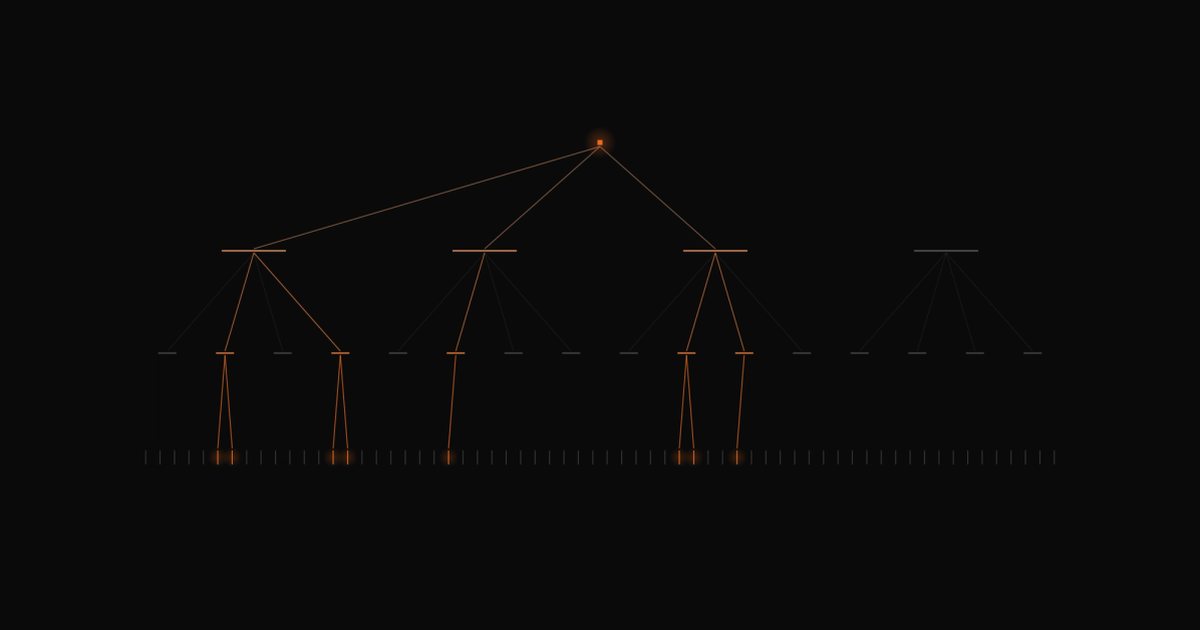
Zyphra introduced Hierarchical Attention (ZHA), which builds a hierarchical tree and searches it to select the relevant tokens for each query, reaching subquadratic complexity. Existing pretrained models are adapted with a distillation phase of only a few billion tokens. Per Zyphra, on RULER-13 at 256K tokens the wide-tree model scores 96.2% (96.0% for the original dense model); on LongBench v2 the deep-tree model scores 63.4% vs 58.0% for dense attention while attending to ~1.1% of the KV cache during decoding.
Source: Zyphra
Need an LLM chatbot or agent for your business?
Describe your need briefly; you will get clarifying questions and a scoped proposal before any work starts.
Related news
AI & LLM · 2026-11-04
Tencent releases Hy4: first vision and computer-use support, aimed at the top tier of open models
AI & LLM · 2026-11-03
LeanGuard: checking every tool call of an LLM agent against a policy written in Lean 4
AI & LLM · 2026-11-03